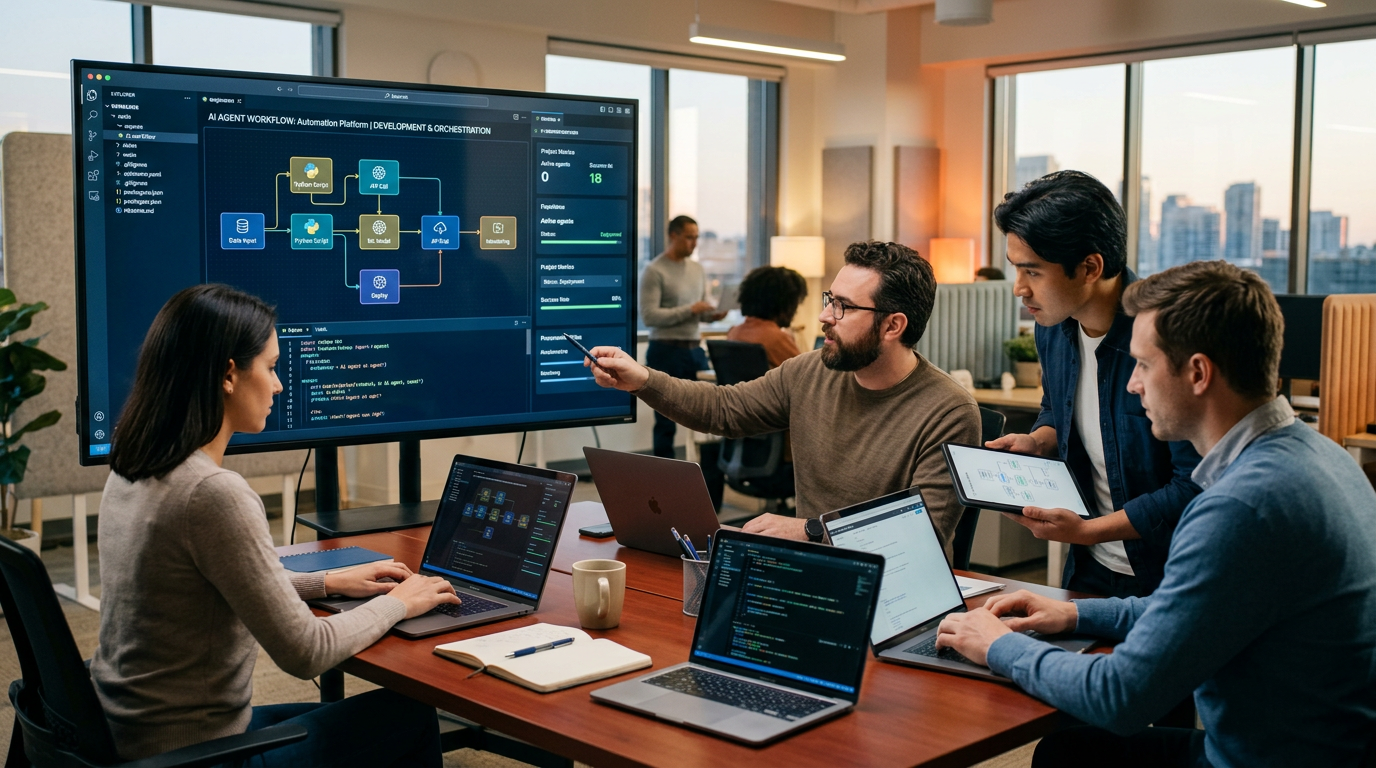
ai agent workflow automation software development is the discipline of designing, building, and shipping software that lets autonomous AI agents carry out multi-step business processes with minimal human input. If you are planning your first build, you are probably wondering where the real work lies and what separates a reliable system from an expensive demo.
Quick answer: Treat it as software engineering first and AI second. Define narrow workflows, give each agent clear tools and guardrails, and build evaluation and observability before you scale usage. Most failures come from unclear process design and missing monitoring, not from weak models.
This guide explains what the discipline involves, why it matters, and which practices and pitfalls decide success. By the end, you will know how to scope, build, and operate an agent workflow without wasting budget.
What is ai agent workflow automation software development?
At its core, ai agent workflow automation software development is the practice of building systems where AI agents plan, decide, and act across connected tools. An agent receives a goal, chooses steps, calls APIs or internal services, and checks results before moving on. The software around it makes that behavior safe and repeatable.
It also helps to separate the agent from the workflow around it. The agent is the reasoning component that picks a next action; the workflow is the deterministic scaffolding that decides when the agent runs, what context it receives, and what happens to its output. Many production systems use an agent for only one or two decision points inside an otherwise conventional pipeline, which keeps behavior predictable while still handling ambiguity where it genuinely exists.
That split explains the vocabulary you will encounter. Tool calling, retrieval, and planning describe agent capabilities; state machines, queues, and idempotent steps describe the surrounding software. Knowing which layer a problem belongs to is the fastest way to scope a build and to explain to stakeholders why a request to "just let the agent handle it" usually needs a workflow decision first.
How agents differ from traditional automation
Classic automation follows fixed rules: if a ticket arrives, assign it to a queue. Workflow agents handle ambiguity. They read a support email, decide whether it is a refund request, look up the order, and draft a reply. That flexibility is powerful, and it is also why agents need stricter controls than scripted bots.
The four layers of an agent workflow stack
In our testing, most production builds share four layers:
- Orchestration: the runtime that routes tasks, manages state, and retries failures.
- Tools: typed functions the agent can call, such as a CRM lookup or a document parser.
- Guardrails: permissions, approval gates, and validation that limit what the agent may do.
- Observability: logs, traces, and evaluations that show what happened and why.
What development work actually involves
Building the model call is the easy part. Most effort goes into process mapping, tool design, error handling, and testing edge cases. A team building a document-processing workflow, for example, spends far more time defining validation rules than tuning prompts. The software engineering discipline is what turns a clever prototype into a dependable system.
Takeaway: plan for orchestration, tools, guardrails, and observability from day one, not as an afterthought.
Why ai agent workflow automation software development matters
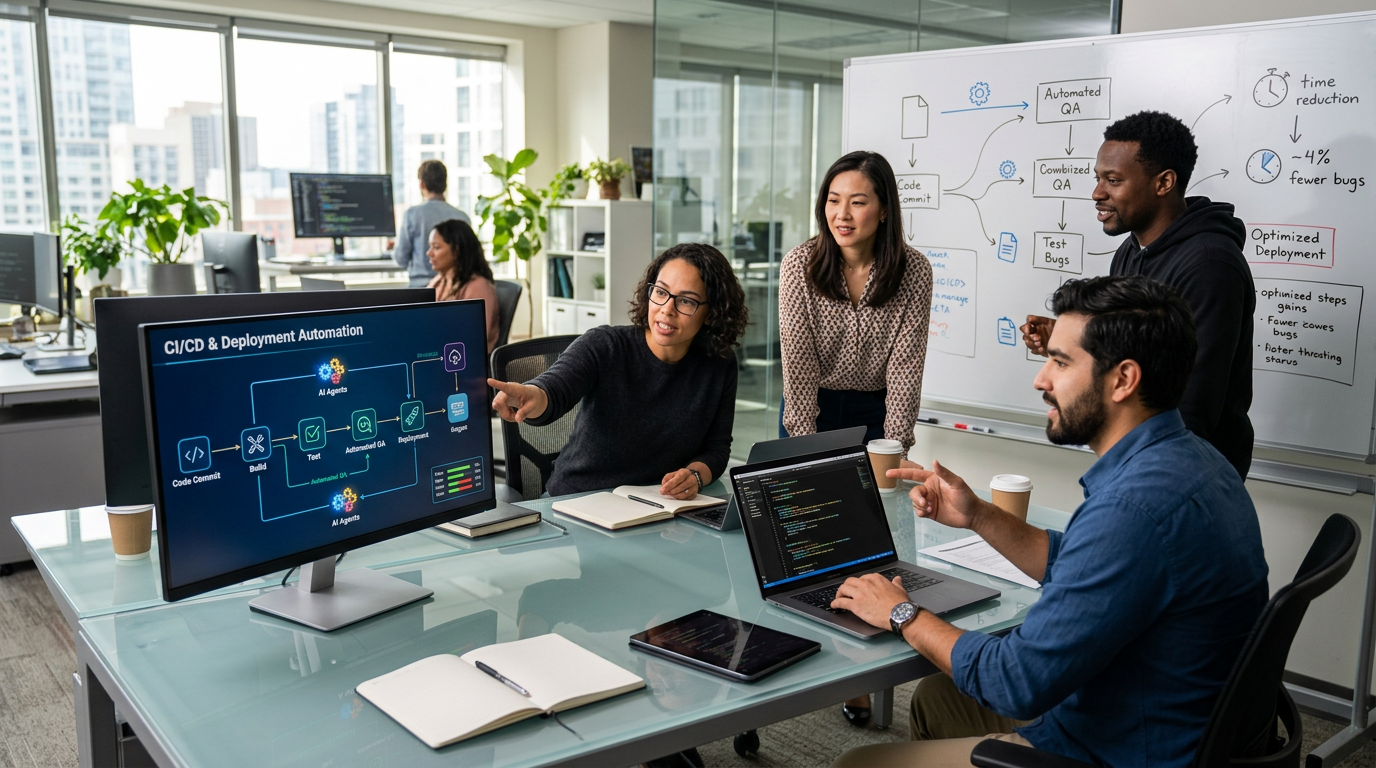
The business case rests on three gains: speed, consistency, and the ability to handle volume that humans cannot scale affordably. Gartner has projected that a large share of enterprise applications will include task-specific agents by 2026, and that agents will increasingly participate in decision-making, not just data retrieval. Those projections vary by analyst, but the direction is consistent.
The competitive angle is less obvious but often larger. Once a workflow is instrumented, you accumulate a record of every decision, correction, and exception that manual teams never captured. That data lets you spot bottlenecks in the underlying process, renegotiate service levels with vendors, and forecast staffing with evidence rather than intuition.
There is also a compounding effect. A well-built orchestration layer and tool library make the second and third workflow cheaper to launch than the first, because guardrails, logging, and evals are already in place. Teams that invest in the platform rather than one-off scripts build a reusable base.
Cost pressure reinforces the point. As model pricing shifts and vendors change terms, the teams that abstracted their model calls behind a stable interface can swap providers without rewriting workflows, while tightly coupled builds face a painful migration.
Where agents deliver measurable value
Teams see results in repeatable, high-volume work. Examples include triaging inbound requests, reconciling invoices, summarizing research, and drafting first-pass responses. Each task has a clear start and end, which makes success easy to measure. Work that is vague or changes constantly tends to deliver poor returns.
The limits you should acknowledge
Agents still hallucinate, misread ambiguous instructions, and struggle with long chains of dependent steps. Cost per task can climb quickly when agents loop or call expensive tools repeatedly. In our experience, the workflows that succeed keep autonomy narrow and escalate to a person when confidence is low.
Why the build approach shapes the outcome
A poorly engineered agent workflow can automate mistakes at scale. A well-engineered one reduces handling time and frees specialists for judgment-heavy work. The difference is rarely the model choice; it is the quality of process design, testing, and monitoring around it.
Takeaway: pursue agent automation for defined, high-volume tasks, and expect to keep humans in the loop for exceptions.
Best practices
Cap the blast radius of any single run. Give each workflow an explicit step ceiling, a wall-clock timeout, and a spend limit, then design the fallback path so a tripped limit routes to a queue rather than failing silently. A reconciliation agent that hits its token cap should hand the case to a person with partial results attached, not vanish.
Reuse a shared tool library across workflows instead of rebuilding lookups for every agent. A single well-tested order-lookup function with stable inputs and outputs cuts duplication and means one fix improves every consumer.
Write runbooks for on-call staff. Include how to inspect a trace, how to pause a workflow, and which alerts signal a genuine regression versus normal edge-case volume. Pair that with a canary rollout: send a small share of traffic to the new version, compare override and error rates against baseline, and promote only when the numbers hold.
Start with the process, not the model
Map the workflow on paper before writing code. Identify decision points, data sources, and failure modes. Pick one narrow process with measurable outcomes, and define what success looks like in numbers. This step alone prevents most scope creep.
Give agents typed, limited tools
Each tool should do one thing and return structured output. Restrict permissions so an agent cannot delete records or send external emails without approval. Small, auditable tools make debugging far easier than one large "do everything" endpoint.
Build evaluations before scaling
Create a test set of real cases with expected outcomes. Run it after every change, and track accuracy, latency, and cost per task. This is where disciplined teams separate from hobby projects; without an eval suite, prompt tweaks become guesswork.
Design human-in-the-loop checkpoints
Route low-confidence decisions to a person, and log what they change. Over time, those corrections become training data and reveal where guardrails need adjustment. A support workflow might auto-send simple replies but queue refunds for review.
Instrument everything
Log every agent step, tool call, and output with trace identifiers. When something fails, you need the full chain, not just the final answer. Pair traces with alerts on error rates and runaway loops.
Takeaway: the best practice list is short: map the process, constrain tools, test continuously, and keep a human gate where risk is high.
Common mistakes to avoid
Another frequent misstep is treating prompts as the product. Teams spend weeks polishing instruction text while neglecting the orchestration layer, then discover that a renamed field in an upstream API breaks the whole chain. Version your prompts alongside your code, tag each change, and connect it to eval results so you can roll back a regression in minutes rather than debugging blind.
Teams also underestimate schema drift. A tool that returns a nested object in January may flatten it by March, and an agent that expected the old shape will silently produce empty fields instead of throwing an error. Validate every tool response against a strict schema and fail loudly when it does not match.
Finally, avoid single-owner builds. When one engineer holds all the prompt knowledge and pipeline context, vacations and departures become outages. Document tool contracts, decision rules, and escalation paths so any teammate can diagnose a stuck run.
Automating an undefined process
If humans disagree on how a task should be done, an agent will not resolve that ambiguity. Teams that skip process design often build elaborate agents around broken steps. Fix the workflow first, then automate.
Giving agents too much autonomy too soon
Broad permissions feel efficient until an agent misclassifies a request and acts on it. Start read-only or draft-only, then expand scope as evals show reliability. This staged approach slows the first launch slightly and saves far more time later.
Skipping cost controls
Looping agents can burn budget fast. Set step limits, token caps, and fallback behavior for every workflow. In our testing, adding explicit retry limits cut one workflow’s cost by roughly half without hurting accuracy.
Neglecting maintenance and drift
Models, APIs, and business rules change. An agent that worked in spring can quietly degrade by fall. Schedule regular eval runs and review traces monthly. Treat the workflow as a living product, not a one-time project.
Ignoring data privacy and compliance
Agents often touch customer records and internal documents. Define what data may leave your environment, and log consent where required. Building compliance in early is cheaper than retrofitting after an audit.
Takeaway: most failures trace back to unclear processes, excessive permissions, and missing cost or compliance controls.
FAQ
How much does it cost to build an agent workflow?
Costs vary widely. A focused internal workflow might take a small team a few weeks; a customer-facing system with strict compliance needs several months. Ongoing model and infrastructure costs often matter more than build costs, so budget for both.
Which processes are a good fit for agents?
Choose repetitive tasks with clear inputs, defined outputs, and measurable success. Triage, data extraction, and first-draft writing fit well. Open-ended strategy work or processes that change weekly usually do not.
Should we use an existing platform or build custom?
Platforms speed up simple, common workflows. Custom builds win when you need deep integration with internal systems or strict control over data. Many teams start on a platform and move to custom code as requirements grow.
How do we measure whether it is working?
Track accuracy against your eval set, human override rates, handling time, and cost per completed task. Compare these against your baseline before launch. Numbers beat impressions.
Do agents replace the team that ran the workflow?
Rarely. They shift the work from execution to review and exception handling. Teams often need fewer people on routine steps and more on quality checks.
Conclusion
Successful ai agent workflow automation software development comes down to engineering discipline: clear processes, constrained tools, continuous evaluation, and honest limits. Agents excel on defined, high-volume tasks and stumble when scope and oversight are vague. The teams that win treat automation as a product with real maintenance needs, not a one-off experiment. Your next step is simple: pick one narrow workflow, map it fully, and build an evaluation set before writing a single line of orchestration code. That small investment will tell you quickly whether the process is worth automating and where the real risks sit.